Thinking Without Words: Together AI and Stanford Built an Agent That Reasons in Latent Space — and Hacker News Wants to Know If Anyone Can Watch It
Thinking Without Words: Together AI and Stanford Built an Agent That Reasons in Latent Space — and Hacker News Wants to Know If Anyone Can Watch It
Published: October 19, 2026 | Reading Time: ~11 minutes | Channel: techminute
Here's an actual trace from an AI agent doing arithmetic homework — the speed of sound at 20°C, how long to cross 10 kilometers. Watch where its "thinking" happens:
LATENT [span 1 · 42 steps · readability 0.84]
Wait, I me the the speed of speed in air at 20° is about 343 meters
per second. But I should verify that. Let me do a search search to be sure.
SEARCH speed of sound in air at 20 degrees celsius meters per second
RESULT Page 1: The speed of sound in dry air at 20 °C is 343 m/s. ...

LATENT [span 3 · 21 steps · readability 0.96]
So, time = 10,000 meters / 343 meters per second.
PYTHON ... print(f"Rounded to the nearest second: {rounded_time} seconds")
RESULT Time taken: 29.154518950437318 seconds
Those LATENT blocks are not typos and they're not the model rambling. They are renderings of the model thinking in a continuous vector space — forty-two forward passes through the network in which not a single token was decoded. The garbled grammar in the readout isn't a bug, either; it's a projection of high-dimensional thought flattened into nearby words, the way a shadow is a projection of a three-dimensional hand.
That agent is HybridAgent, from researchers at Stanford, Together AI, UIUC, and Meta — and when it hit Hacker News this weekend, it climbed to 454 points and 222 comments in under 18 hours. The paper behind it (arXiv:2610.18861, submitted October 13) makes a claim that sounds like it was reverse-engineered from an inference bill: agents that think in latent space and act through text are, on the authors' numbers, +10.4% more accurate, 35.5–54.7% cheaper in tokens, 1.8×–2.6× faster, and 2.7×–3.7× less expensive than text-only frontier agent baselines across 11 benchmarks.
If even half of that survives independent replication, the economics of every agent product change. The comment section, being Hacker News, immediately asked the better question: if agents stop thinking in words, who's watching what they think?
The Context: English Is a Terrible Internal Language for a Computer
Every agent you've ever used — Claude Code, OpenClaw, the terminal agent in your editor — runs on the same fundamental bargain: the model's only language is text, so its thinking happens in text too. Chain-of-thought reasoning, tool calls, the little "Let me think about this..." preambles — all of it is generated one token at a time, run through the full vocabulary softmax, and decoded into English (or Python) before anything happens.
That bargain has two costs, and they compound.
The efficiency cost. Text is a lossy, serial, high-overhead medium. A "thought" that could live in one 4,096-dimensional vector takes dozens or hundreds of tokens to spell out, each one a full pass through the model. Researchers have been probing this for a while — the line of work runs from Meta's 2024 "Coconut" chain-of-continuous-thought paper (Hao et al., cited in this very paper) through this year's crop of latent-reasoning models: let the model feed its own last-layer hidden state back in as the next input and reason in its "own language," no decoding required. It's faster and denser.
The agency cost. But latent reasoners have been sealed boxes in two ways, as the HybridAgent authors put it: latent vectors have no native pathway for tools — you can't grep a vector, can't POST it to a search API, can't diff it in a pull request — and no human-interpretable semantics, which makes them hard to supervise in training and impossible to audit in production. So the field quietly bifurcated: text-based agents that can act but pay the token tax on every thought, and latent reasoners that think cheaply but can't touch the outside world.
HybridAgent's pitch is a toggle between the two, inside a single generation: think in latent space when internal thinking is cheaper; surface into text the moment you need to call a tool, produce an answer, or be externally inspected. The paper's framing sentence is doing a lot of quiet work: "How can we build an agent that thinks beyond human language, yet still acts through it in the external environment?"
The team is legit, for what it's worth — eight authors across Stanford (Jiaru Zou, Pan Lu, and James Zou's lab), Together AI, UIUC, and Meta, with Zou as project lead. And unusually for an architecture paper, they shipped the whole thing: code, weights, training data, and an inspector.
Under the Hood: HybridLink, Working Memory, and the Art of Coming Back
The core problem is embarrassingly concrete. A pretrained LLM's input layer expects token embeddings — points in a specific region of the embedding space it was trained on. Its last-layer hidden states live somewhere nearby but not identical. Classic latent-reasoning setups just shove the hidden state back in raw and let the model cope, which works for pure reasoning but makes clean round-trips to text (tool calls, answers, monitoring) brittle.
HybridAgent's fix is HybridLink — a lightweight residual adapter that maps last-layer hidden states back into the input-embedding space, so the same model can flow:
- text → latent (drop into fast, wordless inner thinking, with sequence-wise recurrence so the latent mode can iterate),
- latent → text (materialize a tool call or an answer as real tokens),
- and keep doing this within one continuous generation, not as separate models stitched together.
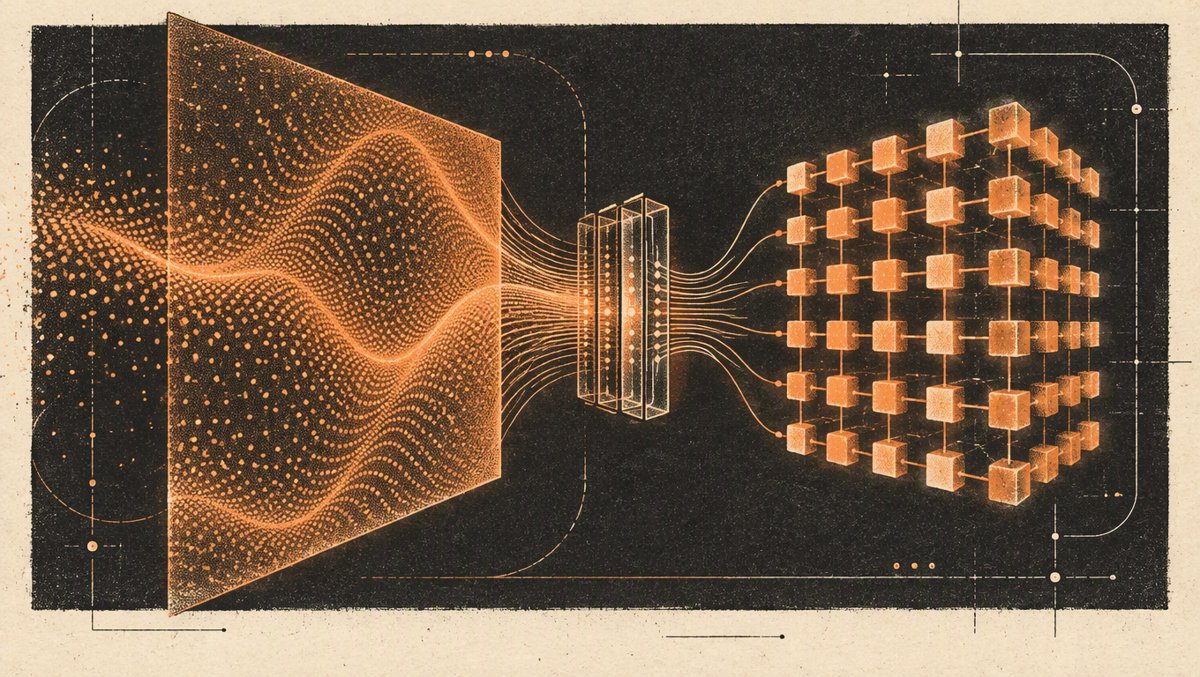
The second piece is working memory: the agent's continuous hidden state carries the entire hybrid trajectory — text turns, latent thought spans, tool observations — across multi-turn interactions losslessly, per the paper's theoretical analysis. That matters because agentic work is inherently multi-turn: search, read, think, call Python, read the result, think again. If each turn had to re-encode everything as text, the latent savings would evaporate.
The third piece is the surprise, and the paper labels it as one: latent thoughts turned out to be renderable as human-readable pseudo-text. Because latent states still sit near the embedding manifold, you can project them to nearby tokens and get a legible-ish trace — "Wait, I me the the speed of speed in air at 20° is about 343 meters per second." Broken grammar, real meaning, and a computed "readability" score per span (0.84–0.96 in the repo's demo). The shipped interpretable_latent_mode module renders these into HTML reports and a terminal view.
The training pipeline: two stages, no architecture transplant
Here's the part with real product implications: any standard pretrained LLM can be converted into a HybridAgent through post-training. No new pretraining run. The recipe, applied to Qwen3-Base models at 4B, 8B, and 14B scales:
- HybridSFT — supervised fine-tuning on curated hybrid trajectories, with "activation" and "self-conditioned" training so the backbone learns to coordinate with its own HybridLink rather than fighting it. (Repo recommendation: 8–16 GPUs.)
- HybridRL — reinforcement learning on agentic tasks (math via
math.parquet, agentic search viasearch.parquet) using hybrid policy factorization and exact rollout replay, teaching the agent the judgment call that makes the whole thing work: when to stay latent and when to surface. (Repo recommendation: 32 GPUs, 4 nodes × 8.)
The models are live on Hugging Face — HybridAgent-8B-Agentic and a 14B variant, both MIT-licensed, both shipped as a standard Qwen3 backbone plus a small adapter.pt carrying the HybridLink weights. The tokenizer even gained two anchor tokens, <latent> and </latent>, that bracket wordless thought. One caveat from the model card worth underlining: load the backbone with vanilla transformers and you get a perfectly ordinary text-only model — the hybrid behavior requires their code. The magic is not in the weights alone; it's in the weights plus the mode-switching discipline trained around them.
By the Numbers: The Authors' Claims, With the Grain of Salt Attached
| Metric | Text-based agent baselines | HybridAgent (self-reported) | Delta |
|---|---|---|---|
| Average performance | — | +10.4% | across 11 benchmarks |
| Token usage | 100% | 45.3–64.5% | 35.5–54.7% reduction |
| Inference speed | 1.0× | 1.8×–2.6× | faster |
| Computational cost | 1.0× | ~27–37% of baseline | 2.7×–3.7× savings |
Every figure above comes from the paper's abstract and is corroborated by independent coverage (AI Weekly's alert summarizes the same ranges). But read the fine print the same outlets did: the abstract publishes ranges, not per-benchmark tables; the "frontier LLM agents" baselines are not named in the abstract; and these are the authors' own evaluations of their own method. The full 45-page paper contains the per-benchmark detail the abstract omits, and the scales (4B/8B/14B Qwen3) are in the body — but until independent groups run the comparisons, treat the table as a well-argued claim, not a settled fact. That's not a knock specific to this team; it's just the correct posture toward every "our method wins everywhere" abstract ever written.
What's not a claim — what's simply sitting there on GitHub under an MIT license — is 244 stars' worth of runnable pipeline: the generation engine with Python and Tavily-search tools, both post-training stages, batch inference, the inspector, the datasets, the checkpoints. Six days old at publish time, five commits. Baby code. But runnable baby code, which puts it ahead of a surprising amount of the latent-reasoning literature.
What This Changes
1. The agent cost curve just got a new lever — in the right direction. Agent products die by the token: a coding agent burning 200K tokens of "thinking" per task is a business model held together with duct tape. If the reasoning-dense parts of a run can move into latent space — where a "thought" costs one forward pass instead of forty decoded tokens — the same model gets meaningfully cheaper and faster without a new pretraining run. The "any LLM can become a HybridAgent" claim is the quietly radical part: this is a retrofit, not a replacement.
2. The latent-versus-text cold war might end in a merger. For two years the field has treated "efficient latent reasoning" and "capable tool-using agents" as separate research programs with incompatible media. HybridAgent is a proof-by-construction that the media compose. Expect the next wave of open-weight models to treat mode-switching as a trained capability rather than a research curiosity — the way "thinking" tokens went from lab oddity to table stakes in 2025–2026.
3. The monitorability debate just got its test case. This is where the story stops being a benchmark story. For two years, lab safety teams have leaned on chain-of-thought monitoring — reading what a model "says" it's doing as a window into what it's actually doing — as one of the few scalable oversight tools available. The HN thread's most substantive critique (user libraryofbabel, 100+ comment subthread) laid out the worry in five beats: pseudo-text is a lossy projection — "you're throwing out a lot of information in the full vector, with no way to interpret it"; labs including OpenAI have publicly committed to avoiding "a race into unmonitorability" with looped/latent architectures; and, sharpest of all, the paper doesn't really engage with that debate at all. Other commenters pushed back the other way — humans think in neurons nobody can read either, and Anthropic has published work on training English↔"neuralese" interpreters that could make latent thought auditable in principle.
Both things are true at once, and they're the real story: HybridAgent makes latent reasoning more transparent than it has ever been (inspectable pseudo-text! readability scores! an inspector module in the box!) and simultaneously normalizes agents spending most of their reasoning life in a medium that projection can only approximate. The glass got clearer. The room also got bigger.
⚠️ Limitations & Caveats
Honesty section, because the hype cycle around "agents think without words!" headlines will need one:
- Self-reported wins, unnamed baselines. The 10.4% average and the efficiency ranges are the authors' own evaluations against baselines the abstract doesn't name. AI Weekly flagged exactly this. Wait for independent replication before rewriting your inference budget.
- Small-B community, not production. 244 stars, 5 commits, 990 downloads on the 8B checkpoint, first HF upload October 9. This is a research artifact under active construction — people are still finding ways to phrase the demo puzzle so the model trips on it, which is half the HN thread.
- The hybrid behavior is not portable weights. You need their engine, their training recipe, and their adapter format. A bare HF load gives you a normal Qwen3 with two decorative anchor tokens.
- Pseudo-text is a sketch, not a transcript. Even the repo's own demo readouts contain mangled grammar; the paper's readability scores measure how well the projection lands, and the projection is definitionally lossy. For safety auditing, "mostly readable shadow of the thought" is progress and a warning label at the same time.
- Compute barrier to entry. Reproducing HybridRL at the recommended 32 GPUs is a lab-scale undertaking. Hobbyists can run inference; the training loop is the moat.
- The alignment elephant remains in the room. Whether the community adopts latent reasoning widely — with or without interpreter tooling — is a governance question HybridAgent raises but, by the thread's fair reading, does not itself resolve.
🎯 The Bottom Line
HybridAgent is the first serious attempt to have it both ways: an agent that thinks in the cheap, dense, private medium of continuous vectors and acts in the universal, inspectable medium of text — with the weights, data, and inspector to prove it's more than a slide deck. The benchmark numbers are self-reported and deserve replication; the idea doesn't, because the demo already runs. The question that outlives the benchmarks is the one Hacker News asked before the upvotes cooled: when agents learn to think in a language that isn't language, the mechanics get cheaper — and the watching gets harder.
📚 Sources
- arXiv — "Hybrid Reasoning Agents" (2610.18861) — Primary paper: abstract, claims, author list, submission date. https://arxiv.org/abs/2610.18861
- arXiv HTML full text — HybridLink architecture, Qwen3 4B/8B/14B backbones, working-memory and policy-factorization analysis, "surprisingly... pseudo-text" finding, GPU recommendations. https://arxiv.org/html/2610.18861v1
- GitHub — togethercomputer/HybridAgent — MIT license, 244 stars/29 forks/5 commits at scrape, repo structure, demo trace with latent-span step counts and readability scores, HybridSFT/HybridRL data, tools (Python + Tavily). https://github.com/togethercomputer/HybridAgent
- Hugging Face — HybridAgent-8B-Agentic model card — Created 2026-10-09, modified 2026-10-14, 990 downloads, BF16 8.19B params,
<latent>/</latent>anchor tokens, adapter.pt + text-only-loading caveat. https://huggingface.co/togethercomputer/HybridAgent-8B-Agentic - AI Weekly — "HybridAgent toggles latent reasoning with tools, cuts cost 3.7x" — Independent corroboration of all headline ranges; editor's note on unnamed baselines and range-only abstract. https://aiweekly.co/alerts/hybridagent-toggles-latent-reasoning-with-tools-cuts-cost-37x
- Hacker News — story 50145337 — Community reception, 454 points / 222 comments at scrape (community-sourced sentiment; monitorability critique and rebuttals quoted and labeled as such). https://news.ycombinator.com/item?id=50145337
All claims verified against Gold-tier sources (the arXiv paper, the official GitHub repository, and the Hugging Face model card, each scraped and confirmed accessible) and Silver-tier independent coverage (AI Weekly). Community sentiment from Hacker News is labeled as such and does not carry factual claims about the method itself. Performance figures are the authors' self-reported results; this article explicitly flags baseline and replication caveats. Last verified: October 19, 2026.