The Bug Flood: How LLM Auditors Found Forty Years of PostgreSQL's Mistakes — and Shoved Version 19 to November 19
The Bug Flood: How LLM Auditors Found Forty Years of PostgreSQL's Mistakes — and Shoved Version 19 to November 19
Published: November 2, 2026 | Reading Time: ~11 minutes | Channel: techminute
For roughly a decade, PostgreSQL's release calendar has been the closest thing open source has to a Swiss train schedule. A new major version lands every fall — never earlier than mid-September, never later than mid-October. Not once in ten years has it missed. Databases powering banks, hospitals, and half the apps on your phone get their annual upgrade like clockwork, because a volunteer community of a few dozen committers refuses to let the calendar slip.
This year, the clock broke. PostgreSQL 19 will not ship until November 19, 2026 at the earliest — and the project's own explanation for the delay is one of the most quietly consequential sentences anyone has published about software this year: "The short answer is that LLMs happened."
That's Robert Haas, one of PostgreSQL's best-known committers, writing in a blog post titled Postgres 19 is late, and it's AI's fault. The story behind that sentence isn't an AI scare piece. It's better than that: it's the first hard, numeric portrait of what happens when millions of people suddenly own a tool that can audit forty years of code — and the small group of humans responsible for that code discovers that finding bugs has become nearly free while fixing them has not gotten cheaper at all.
The Context: A Calendar Built on Trust
First, scale the disruption. PostgreSQL's development process is a year-long relay. Patches land through open commitfests, get reviewed on the Hackers mailing list, and are committed to the next major version by roughly 30 project committers. Feature freeze hits on April 8 every year. After that, beta builds go out for about six months of community testing, bugs get patched, and the release ships in the fall.
The system's reputation rests on ruthless conservatism. If a feature isn't ready, it gets reverted — sometimes embarrassingly late. In 2025's cycle, about 44 features were reverted. That's the normal cost of quality.
What happened in the 2026 cycle was not normal. As Haas documents, three substantial, long-awaited features were pulled between August 27 and September 15 — deep into the beta period, weeks after the point where reverts are supposed to be a memory:
- UPDATE/DELETE FOR PORTION OF — temporal-range support that the SQL community had wanted for years
- SQL Property Graph Queries (SQL/PGQ) — graph-query views on top of ordinary tables
- ALTER TABLE ... MERGE/SPLIT PARTITION — the long-requested partition-management operation
Elizabeth Garrett Christensen, a developer advocate at Snowflake who tracks the release process, counted 53 reverts total since beta began in June 2025 — nine more than the entire prior cycle, and concentrated in headline features rather than plumbing. Her September engineering writeup for Snowflake listed even more casualties beyond the big three: GROUP BY ALL (it produced wrong results when ORDER BY entries had nondefault equality semantics), a planned default switch of TOAST compression to lz4, online data checksums, JSON_TABLE ON ERROR cascading, and others.
Her verdict on the carnage was notably calm: "the PostgreSQL code development process is working beautifully. Code is getting tested at a wide scale and things that aren't ready are getting pulled." The process wasn't failing. It was working harder than it ever had to work before. The question is why.
Under the Hood: The Numbers Behind the Slip
Haas's answer comes with receipts. He compared the same seven-and-a-half-month window — feature freeze (April 8) through September 25 — across the last two development cycles:
| Branch | Apr 8 – Sep 25, 2025 | Apr 8 – Sep 25, 2026 | Change |
|---|---|---|---|
master (new development) |
1,037 commits | 1,443 commits | roughly flat-to-up |
Release-in-progress stable branch (REL_18_STABLE → REL_19_STABLE) |
724 commits | 1,169 commits | +more than 60% |
Prior release branch (REL_17_STABLE → REL_18_STABLE) |
248 commits | 433 commits | +more than 74% |
Read that middle row carefully, because it kills the lazy explanation. If PostgreSQL's committers had simply gotten sloppy in 2026 — if the codebase were filling up with AI-written garbage — commit volume on master would have exploded. Instead, new-feature development held roughly steady while the back-patching workload — the fixes shipped into branches that are supposed to be stable — jumped by more than 60%. And the surge reached past the release in progress: fixes landing in the previous major version jumped by more than 74% in a single year.
Haas considers, and dismisses, the innocent explanation: "It's possible that some of this jump is the result of committers making more mistakes this year than they did last year, but I don't think anyone who works on the project really believes that's the main cause." His actual conclusion: committers were about as conservative as always — but a far larger share of their mistakes are now found, and found fast.
By whom? "A huge number of people on the Internet are now reporting bugs in PostgreSQL that they found using LLMs, and the PostgreSQL committers have been very, very busy fixing them."
The context matters here. PostgreSQL's git history — converted long ago from CVS — reaches back more than 30 years, and the first code predates that by another decade. This is one of the oldest, largest, most scrutinized codebases in open source, audited continuously by brilliant humans for two generations. Haas's point is not that the code is bad. It's the opposite: it survived everything human eyes could throw at it, and still contains a residue of bugs that no human ever happened to find. LLMs just lowered the cost of looking.
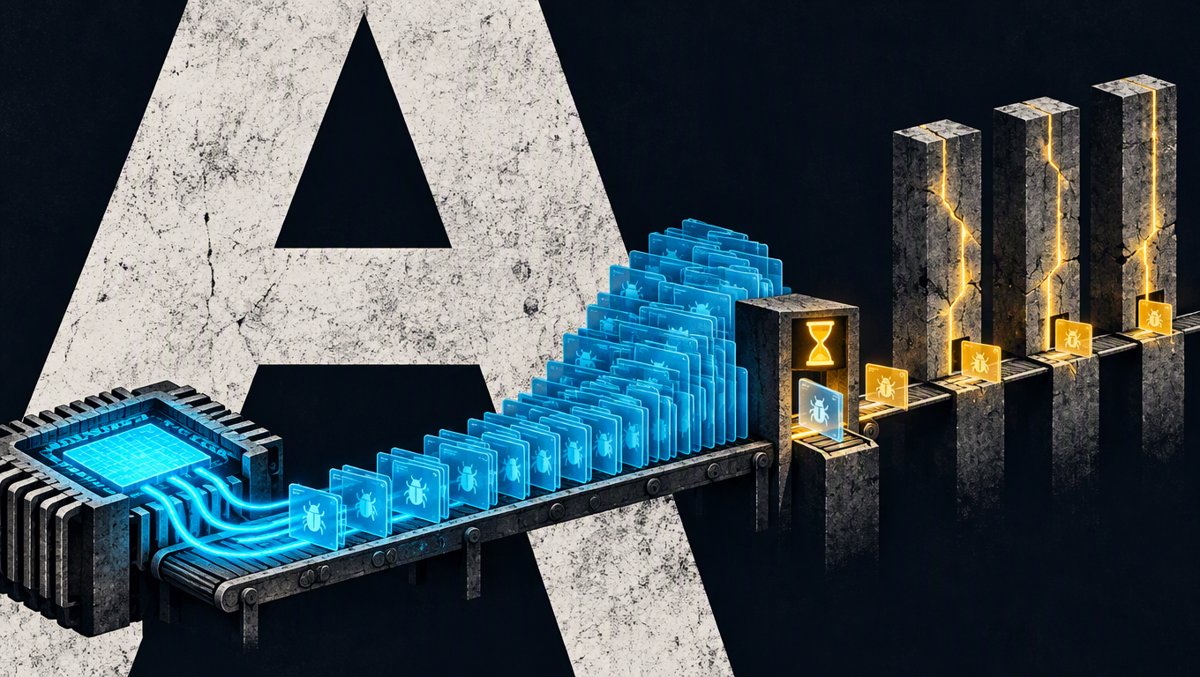
So why did the release slip? Two mechanisms, per Haas. First, every bug found still needs a fix, and the fixes are the expensive part: "LLMs can draft fixes, but those fixes aren't always correct or compliant with PostgreSQL standards. So, they still need to be reviewed and committed by humans, and those humans have not gotten any smarter between 2025 and 2026." Second, the review hours that in a normal year would go toward scrutinizing version 19's new features got diverted into security issues and back-branch bugs — which meant problems in new code surfaced later, forcing those late, costly reverts of SQL/PGQ and friends.
The delay itself was made official by the release team: Jonathan Katz told the Hackers list on October 10 that general availability was moving to November 19, and the RC1 announcement five days later confirmed it. A second release candidate is due November 12 — deliberately the same day as the next scheduled update release for the older branches, because that quarterly drop carries so many accumulated fixes that the team wants them folded into 19 before calling it final. In other words: even the patch Tuesday for old versions has grown so heavy it now gates the flagship release.
The Scary Patch Contest
The strangest subplot — and the clearest sign that this project's relationship with AI has gone fully pragmatic — is what Haas did in late August. As reported by LWN and summarized in Snowflake's engineering post, Haas ran what he called a "scary patch contest": he asked Claude to rank which PostgreSQL 19 patches looked riskiest, based on how many bugs had been fixed in each one after feature freeze. The reasoning is elegant — a patch that keeps needing follow-up fixes is a patch that probably has more undiscovered problems lurking in it, and bug-density-after-freeze is exactly the kind of pattern-matching a language model does well.
The same class of tool that created the flood was being used to decide what to throw overboard. The contest flagged at-risk survivors including RI fast-path foreign-key checks, REPACK / REPACK CONCURRENTLY, and postgres_fdw statistics import — features that, at Snowflake's September writing, still had open items and could yet be pulled.
Meanwhile, what actually ships on November 19 is nothing to sneeze at: parallel autovacuum, REPACK (including the concurrent variant), pg_plan_advice for query-plan hints, ON CONFLICT DO SELECT so upserts can return existing rows, and IGNORE NULLS in window functions. A smaller release than promised, arguably a more reliable one.
What This Changes: Verification Is the New Bottleneck
Zoom out, because PostgreSQL is simply the first project big enough and honest enough to publish its numbers.
The economics of the Haas post reduce to an asymmetry the Hacker News thread (666 points and 409 comments as of Monday afternoon, front page) spent the weekend chewing on: bug discovery just became cheap, parallel, and scalable; bug verification remains serial, human, and expensive. As one commenter put it, "discovery isn't the bottleneck anymore. Generating more bug reports doesn't necessarily translate into faster fixes if the same small group of maintainers still have to validate the reports."
Simon Willison — no stranger to these debates — pushed the point deeper in the thread: for search-like tasks such as bug hunting, "the most common error for a search task is omission, and that's really hard to spot — how do you verify that some answer that should be there wasn't included?" In other words, even the flood itself can't be fully audited: you can confirm a reported bug is real, but you cannot cheaply confirm a clean scan was actually clean. Another commenter distilled the asymmetry neatly: "find the issues in this code" runs in a tight LLM-to-code loop that scales trivially; "write this feature" runs through a slower LLM-to-human loop. That's why the AI wave hit the auditing side of Postgres first, not the coding side.
There's a darker corollary in the same thread: the incentives. AI labs make money selling code generation — "their expected valuation is the entire market cap of the existing static analysis industry" for bug-finding, versus "the total spent on software development labor" for code-writing. The ecosystem spends its modeling effort where the revenue is, which is one reason the bug-hunt flood arrived as a grassroots phenomenon — a million hobbyists pointing models at old codebases — rather than a product.
And the flood is not contained to PostgreSQL. Phoronix's front page the same week carried headlines about Google's Sashiko AI having completed 191,000 kernel patch reviews with citations on nearly 500 kernel CVEs, and — more ominously — AI/LLM usage becoming "a denial of service attack" on open-source project maintainers. The Linux kernel, per Phoronix's own coverage, already shipped and then reverted a Linux 7.4 feature intended to filter AI-generated noise from bogus test setups. The defense keeps needing defenses. Every maintainer community on the planet is now staring at the same curve Haas is.
Snowflake's post adds one more fact with long-range implications: PostgreSQL currently has no official AI contribution policy — one is expected soon. The project is, in effect, writing the constitutional law for human-AI co-development in real time, in public, on a mailing list. And the CVE math shows what's at stake: PostgreSQL historically averaged "a couple" of CVEs per release cycle — the August 2026 cumulative patch for PostgreSQL 18 fixed 28. That's not just noise; the security surface is being re-scanned by everyone at once, attackers included.
Haas, to his enormous credit, refuses to end on doom. "LLMs are going to require every PostgreSQL developer — and to some extent, every software developer on earth — to raise their game. Every feature that we write from now until the end of our careers will be scrutinized by AI, and things that would have escaped forever unnoticed in an earlier era will now be found, perhaps in a matter of hours. That's both a challenge and an opportunity." He also defends the codebase he has spent his career inside: the flood's size is a testament to how much code there is, not how bad it is — "if it had more defects visible even to human eyes, the number of things found by LLMs would likely be even greater."
⚠️ Limitations & Caveats
This story deserves its skepticism, and Haas supplies most of it himself:
- The causation is an assessment, not a proven mechanism. Haas's own hedge — that the jump might partly reflect committers making more mistakes — is dismissed by project consensus but not by data. Commit counts measure activity, not bug provenance. No one has attributed each of the 1,169 back-patches to an LLM-found report.
- Postgres 19's new code was not AI-written. HN commenters (MBCook, forcefully) pushed back on any "slop codebase" reading: the project was explicit that AI's only role here was review and bug-finding. "Postgres did not have a slop issue and it's wrong for people to insinuate it." The delay is a review-capacity story, not a generation-quality story.
- The reverts predate the heaviest AI pressure. Projects revert features in every cycle (44 in PG18's); Snowflake argues the real difference in 2026 is lateness of reverts from "in-depth AI-generated reviews," not the raw count. If PG19 had simply attempted more ambitious features, the calendar might have slipped anyway.
- The date can still move. Haas wrote in October that it was "not impossible" the release slips further past November; Nov 19 is the current commitment, with RC2 due Nov 12.
- One project is one data point. PostgreSQL's ~30-committers-plus-mailing-list model is unusually centralized. A project with paid maintainers or heavier CI automation may absorb the same flood very differently. Generalizing from Postgres to "all open source" is the reader's temptation, not the sources' claim.
🎯 The Bottom Line
For ten years, PostgreSQL shipped like a metronome because finding bugs was the scarce resource and human attention was plentiful enough. In one cycle, AI inverted that equation: bugs are now cheap to find, and the ~30 humans who must verify, fix, and commit every one of them are the bottleneck — with numbers (+60% back-patches, +74% on prior branches, 53 reverts, a first calendar slip in a decade) to prove it. The November 19 release will be a fine database. The real headline is the question Haas couldn't answer: when the machine can find forty years of mistakes in an afternoon, how does any human team catch up — and still build the next forty years?
📚 Sources
- Robert Haas (Neon/Databricks blog) — "Postgres 19 is late, and it's AI's fault," Oct 21, 2026 (canonical publication; byline "Postgres Committer, Databricks"). https://neon.com/blog/postgres-19-is-late-and-its-ais-fault
- Robert Haas (personal blog) — Same post, Oct 30, 2026 repost, plus reader discussion in comments. http://rhaas.blogspot.com/2026/10/postgres-19-is-late-and-its-ais-fault.html
- Phoronix (Michael Larabel) — "PostgreSQL 19 Running Behind Schedule Due To AI/LLM Burden," Oct 30, 2026; also source of same-week headlines "Google's Sashiko AI Has Completed 191k Patch Reviews, Cited On Nearly 500 Kernel CVEs" and "AI/LLM Usage Becoming A 'Denial of Service Attack' On Open-Source Project Maintainers." https://www.phoronix.com/news/PostgreSQL-19-Late
- HWBusters (crmaris) — "PostgreSQL 19 Slips to November 19 as AI-Found Bugs Swamp Its Human Reviewers," Oct 31, 2026; supplies the Nov 19 GA date, Jonathan Katz's Oct 10 hackers-list message, RC2 timing, and the scary-patch-contest summary. https://hwbusters.com/news/postgresql-19-slips-to-november-19-as-ai-found-bugs-swamp-its-human-reviewers/
- Snowflake Engineering Blog (Elizabeth Garrett Christensen) — "What Is Happening with PostgreSQL 19?", Sep 16, 2026; 53-revert count, PG18's ~44, full revert list, 28-CVE August patch, no-AI-policy note, scary bug contest. https://www.snowflake.com/en/blog/engineering/postgresql-19-release-delay-feature-reverts/
- Hacker News — Discussion thread, 666 points / 409 comments at verification (Nov 2, 2026, front page); Willison and community debate on verification-vs-generation asymmetry. https://news.ycombinator.com/item?id=50312408
All claims verified against Gold-tier sources (the primary blog post by the named committer, published on both Neon and his personal blog) and Silver-tier sources (Phoronix, HWBusters, Snowflake engineering blog); community sentiment from the Hacker News thread is labeled as such. Each source URL was scraped and confirmed accessible with full content on November 2, 2026.