The Ban and the Gift: DeepSeek Just Open-Sourced the Engine That Runs Its AI — Days After Washington Kicked It Out
The Ban and the Gift: DeepSeek Just Open-Sourced the Engine That Runs Its AI — Days After Washington Kicked It Out
Published: October 20, 2026 | Reading Time: ~11 minutes | Channel: techminute
On Monday, the U.S. Department of Homeland Security issued a notice ordering every federal civilian agency to strip DeepSeek's technology out of its IT systems — not just the company's own products, but any third-party tools built with DeepSeek's models. The Treasury, State, and Justice departments, plus every prime contractor serving those agencies, are covered.
Less than 24 hours later, the thing everyone on Hacker News was actually reading was something else entirely: DeepSeek had open-sourced DeepInfer, the inference engine that powers its own large-scale production services. By Tuesday afternoon the repository had 8,200 stars and 685 forks on three commits, Apache-2.0 licensed, and the Hacker News thread ("DeepSeek just open-sourced its inference engine") sat at 1,077 points with 371 comments — the #1 story on the front page.
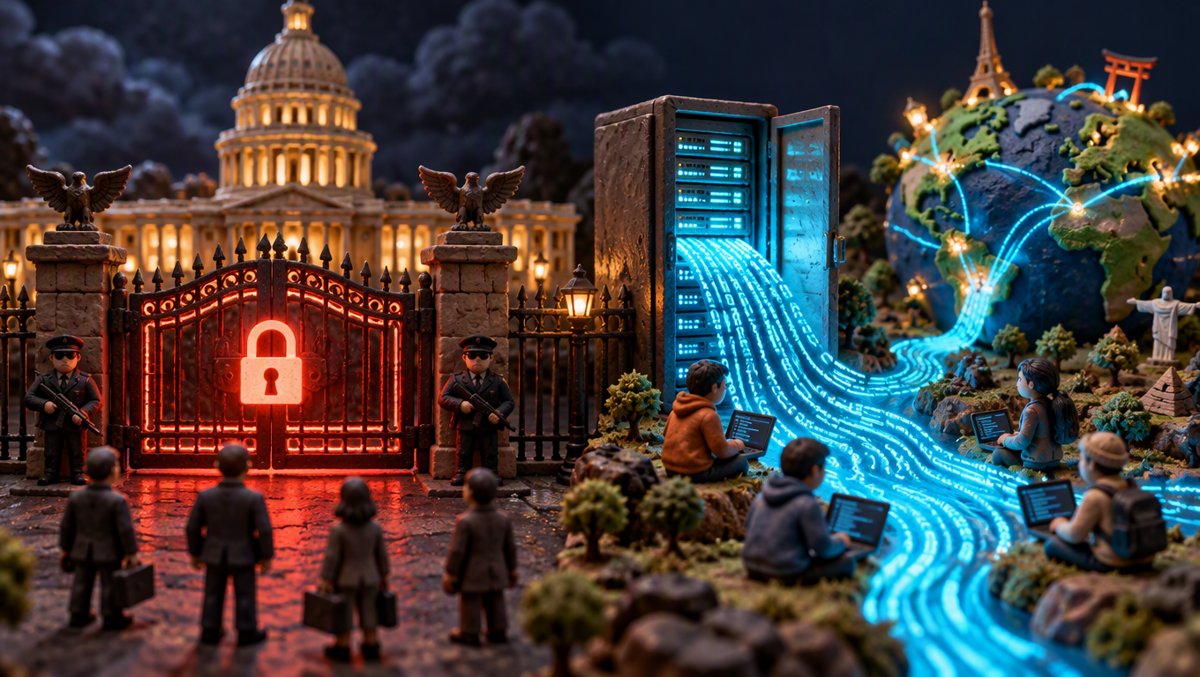
One lab, one week: a new model released, banned from Washington's civilian systems, and then the serving stack underneath it handed to the world for free. You don't need a foreign policy degree to see the shape of that joke. But the engine itself is the real story — because of what's in it, and especially because of what hardware it runs on.
The Context: What Led to This
First, the ban. On Monday, DHS posted a notice directing federal civilian agencies to remove DeepSeek products from their devices — and, crucially, products "created using DeepSeek by third parties." As The Guardian reported, a document attached to the notice states flatly that "DeepSeek's models present multiple threat vectors," and warns that using them "may result in the transfer of sensitive data to [China] if used by US government employees or vendors." The core worry is jurisdictional: DeepSeek's servers sit in China, where the state has "extensive authority" to access private company infrastructure.
The details in the notice are more granular than the headlines suggest. As ITPro's Emma Woollacott documented, DHS says DeepSeek's account generation "collects personally identifiable information (PII) and may also track and digitally fingerprint users," and that data flowing to the PRC "could produce actionable intelligence on US persons and/or government programs." The notice also cites open-source security research finding multiple critical vulnerabilities in the DeepSeek iOS app — and tells agencies that already used DeepSeek to check whether they've been compromised: monitor traffic, implement enhanced logging, flag anomalous activity.
This didn't come from nowhere. Texas, New York, and Virginia already banned DeepSeek from state systems, as did Australia, South Korea, and Taiwan. The Commerce Department and the U.S. Navy had removed it from their own environments earlier. What's new is the scope: an entire tier of the federal civilian government, plus its contractors, plus — the part making security people sweat — anything derived from DeepSeek models. Gabrielle Hempel, a security operations strategist at Exabeam, told ITPro the breadth "raises some significant questions about software provenance and supply-chain compliance," and predicted "increasing tension between national security policy and the practical realities of AI development."
Now the gift. DeepInfer's README describes it without flourish: "the high-performance inference framework that powers DeepSeek's large-scale production services." This is not a research toy or a demo repo. It is (a version of) the machinery that serves one of the world's most heavily used open model families, and it just landed on GitHub under a permissive license. The release is scoped to offline inference — "the core features needed for serving at scale" — and is built for exactly one model family: DeepSeek-V4.1-Flash, with the default checkpoint being deepseek-ai/DeepSeek-V4.1-Flash-1017, the fast, lightweight V4 refresh released just days before the ban, per ITPro.
To understand why developers care, remember what an inference engine is. Training gets the headlines, but serving is where models live: the kernel code, schedulers, and sampling logic that turn a pile of weights into tokens per second at a price someone will pay. That layer has been dominated by vLLM, SGLang, and NVIDIA's TensorRT-LLM. DeepInfer's acknowledgments are disarmingly honest: it was "originally built primarily on vLLM, with additional inspiration from SGLang and TensorRT-LLM." The student just published its homework — and the homework runs a frontier lab's production traffic.
Under the Hood: What's Actually in the Repo
The feature list reads like a tour of what actually matters when you serve models at DeepSeek's scale:
- Optimized kernels with names you know. FlashMLA (DeepSeek's own MLA attention kernel), DeepGEMM, DeepEP (its expert-parallel library), TileKernels, DeepSelect, and custom TileLang kernels. If you've followed DeepSeek's open-source strategy, these are the same building blocks it has been drip-releasing since early 2025 — now wired into one coherent stack.
- Speculative decoding with a scheduler that reads the room. "DSpark and confidence-scheduled verification" accelerates decoding with draft tokens, then uses confidence estimates to decide when to bother verifying. Draft length defaults to 5 tokens, tunable via
DEEPINFER_USE_NEXTN_DECODE. Speculative decoding is a standard trick; scheduling the verification pass by confidence rather than blindly is the interesting part. - SWA bounded replay. Decoder prefill work gets cut down by replaying only a bounded suffix of the context — 140 tokens kept by default (
DEEPINFER_YOCO_PREFILL_KEEP_TOKENS=140) — enough to cover the sliding-window attention span plus maximum backtracking. It's the kind of unglamorous optimization that compounds into real money at scale. - Batch-invariant inference and deterministic sampling. A flag (
DEEPINFER_BATCH_INVARIANT=1) makes results identical across different batch compositions, and deterministic sampling produces identical outputs for identical inputs and seeds. This is a bigger deal than it sounds: it's the difference between "the model said X during my eval" and "the model says X, full stop" — reproducibility that batched GPU serving normally sacrifices for throughput. NVIDIA-only for now. - Structured outputs. Generation can be constrained to a regex, a JSON schema, or an EBNF grammar via sampling parameters. That's table stakes for agent pipelines, and its presence tells you who this engine is for.
- An asynchronous scheduler the README calls "zero-overhead," overlapping CPU batch scheduling with device execution, enabled by default.
The repo tree is as revealing as the feature list. There's a requirements-ascend.txt sitting right next to requirements-nvidia.txt. Which brings us to the geopolitical heart of this story.
The Part Washington Should Actually Read: Two Accelerators, One Engine
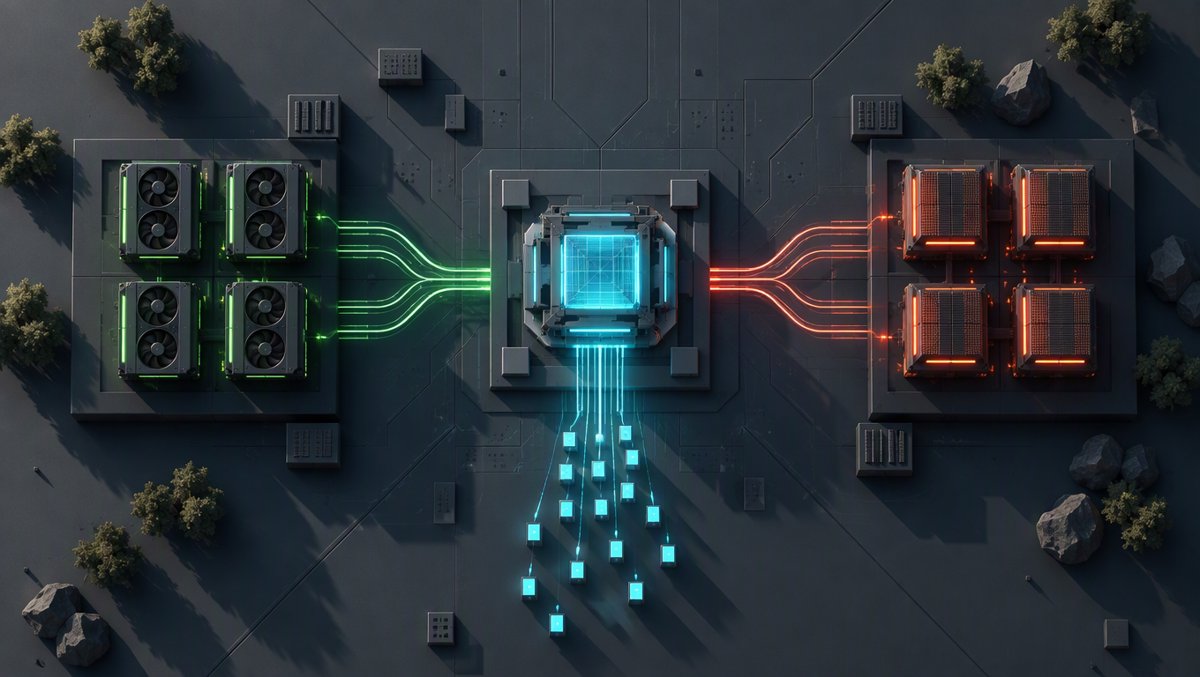
DeepInfer supports two hardware targets: NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. Building requires CUDA 13 on the NVIDIA path or CANN 9.2 — Huawei's software stack — on the Ascend path. Benchmarks in the README were measured on 4 SM100 GPUs for prefill and 64 for decode (the per-GPU throughput numbers render as tables that don't survive text extraction, so treat the specific figures as unpublished until someone runs run_sweep.sh and publishes).
Think about who needs that dual support. The U.S. ban does not stop DeepSeek from operating — it stops U.S. government systems from consuming. But it fits a broader squeeze: export controls on advanced accelerators, an ongoing U.S. accusation — relayed in the Guardian's coverage — that DeepSeek and other top Chinese labs have been "systematically stealing the capabilities of cutting-edge models developed by American rivals," and a federal government signaling that DeepSeek-hosted anything is persona non grata. A lab in that position has rational reasons to make sure its serving stack runs equally well on domestic silicon — and to make the whole thing Apache-2.0 so that every company, university, and government ministry outside the U.S. federal system can adopt it, fork it, and build on it without asking permission.
To be clear: DeepSeek has not stated its motives, and nothing in the repo or the coverage confirms any of this framing. It's inference, not policy. But the release schedule does the narrating for it. A new model drops. Washington bans the ecosystem it anchors, including derivatives. Within roughly a day, the engine that serves it is open source and sitting at #1 on Hacker News. And per the Guardian, this is all landing in the run-up to a scheduled November summit between Trump and Xi in Shenzhen — following a September White House meeting where the two countries agreed to establish a "communication channel" for AI incidents. The engine release is not on any diplomatic agenda. It doesn't need to be.
China's government, for its part, slammed the ban — Reuters, the BBC, and Fox Business all carried Beijing's response on Monday, and the ban's defenders and critics spent the day relitigating 2025's "DeepSeek moment," when the lab's low-cost, high-performance chatbot upended assumptions about U.S. AI dominance.
By the Numbers
| Metric | Figure | Source |
|---|---|---|
| Hacker News points at check | 1,077 | HN story 50163277 (via Algolia API) |
| HN comments | 371 | same |
| GitHub stars within hours | 8.2k | repo page |
| GitHub forks | 685 | repo page |
| Commits at release | 3 | repo page |
| License | Apache-2.0 | LICENSE |
| Supported models | DeepSeek-V4.1-Flash (checkpoint -1017) |
README |
| Hardware targets | NVIDIA SM100 / Huawei Ascend 950 | README |
| Default speculative draft length | 5 tokens | DEEPINFER_USE_NEXTN_DECODE |
| Default SWA replay suffix | 140 tokens | DEEPINFER_YOCO_PREFILL_KEEP_TOKENS |
| Benchmark rig | 4 GPUs prefill / 64 GPUs decode | README |
| Ban scope | All federal civilian agencies + contractors + third-party derivatives | DHS notice via Guardian/ITPro |
What This Changes
For the inference ecosystem: a fourth major open serving stack just appeared — and unlike most, it ships with production pedigree and honest lineage. vLLM and SGLang will feel this first; expect cross-pollination (and probably some kernel-licensing drama) within weeks.
For supply-chain compliance: the derivative-tools clause is the sleeper. If "built using DeepSeek" triggers removal, then every product with a DeepSeek-influenced distilled model, a DeepSeek-generated embedding, or — who knows how broadly this gets read — a component compiled with DeepInfer is suddenly a compliance question. Hempel's warning is the right one: the hard part isn't the policy, it's "making those requirements sufficiently clear and technically enforceable." Open-sourcing the engine the same week makes that enforcement harder, not easier, because provenance now flows through a thousand forked repos.
For the hardware map: an inference engine that treats Ascend 950 as a first-class target is a quiet infrastructure bet on Chinese silicon being good enough — and on a world where the U.S. government is one increasingly isolated node of DeepSeek non-consumption.
⚠️ Limitations & Caveats
Honesty time, because the repo's own README does some of it for us:
- This is not a complete serving stack. The README lists what a "complete inference service" requires that is not included: a KV cache system, prefill/decode disaggregation, and load balancing across data-parallel replicas. It concedes "most required engine functionality is already implemented" — but if you clone this today, you get offline inference, not DeepSeek's production service. The crown jewels stay home.
- Hardware narrowness cuts both ways. SM100 is NVIDIA's current-generation Blackwell class — most of the world's installed GPU base can't run this. And the Ascend path requires CANN 9.2 on a very recent NPU. Nobody's serving this on a laptop.
- The environment is opinionated. Linux, GCC 13+, Python 3.12, CUDA 13. There will be pain before there are benchmarks from the community.
- No stated motive, no attribution. Any "DeepSeek is making a geopolitical statement" reading — including mine — is interpretation. The repo doesn't editorialize.
- The ban's practical bite is unproven. DHS directs civilian agencies; per the Guardian, it cannot bind the military or intelligence services, and history suggests compliance, replacement costs, and edge cases (what about a tool that touched DeepSeek output once?) will be contested for months.
- Benchmark numbers are currently unextractable. The README's performance tables didn't survive scraping; claims about throughput should wait for independent
run_sweep.shruns.
🎯 The Bottom Line
Washington just drew the tightest circle yet around DeepSeek's technology — and DeepSeek responded by widening the aperture, handing the world the engine that serves its models, permissively licensed, running on both American and Chinese accelerators. The ban governs what U.S. federal systems may consume; the open-source release governs what everyone else may build. Between those two forces sits the actual market, and as of Tuesday, it has 8,200 reasons to pay attention.
📚 Sources
- GitHub — deepseek-ai/DeepInfer — Primary source: README (features, hardware support, environment, not-included list), license, repo metrics. https://github.com/deepseek-ai/DeepInfer
- The Guardian (AFP) — DHS notice, threat-vector and data-transfer quotes, civilian vs. military scope, U.S.–China context, November Shenzhen summit. https://www.theguardian.com/us-news/2026/oct/20/us-bans-china-deepseek-ai-tools-government-agencies
- ITPro (Emma Woollacott) — Ban scope (Treasury/State/DOJ, contractors), PII/fingerprinting notice text, iOS vulnerabilities, Exabeam's Gabrielle Hempel analysis, prior state and international bans, V4.1-Flash-1017 timing. https://www.itpro.com/security/us-bans-deepseek-from-federal-civilian-agencies
- Hacker News — Community signal: "DeepSeek just open-sourced its inference engine," 1,077 points / 371 comments, #1 front page Oct 20 (retrieved via Algolia API). https://news.ycombinator.com/item?id=50163277
- Reuters — Corroboration: "US banning Chinese AI DeepSeek from government agency IT systems" (Oct 19). https://www.reuters.com/technology/us-banning-chinese-ai-deepseek-government-agency-it-systems-2026-10-19/
- BBC News — Corroboration: "US bans China's DeepSeek from government in race for AI dominance." https://www.bbc.com/news/articles/cjkgeq0k1wevo
All claims verified against Gold-tier (official GitHub repository) and Silver-tier (The Guardian, ITPro, Reuters, BBC) sources, each scraped and confirmed accessible. Community figures (Hacker News) labeled as community-sourced. HN discussion thread itself returned HTTP 419 to scraping and was verified via the Algolia API instead. Last verified: October 20, 2026.