In mid-September, a small startup called TypeSafe AI shipped Jev — a closed model that doesn't chat, doesn't write code, and only returns answers and choices. I covered it here three weeks ago as a curiosity: a "System One" model for software that needs verdicts, not essays. Twenty days later, that curiosity has become a land-grab. On October 1, Perplexity quietly released pplx-decider-v1-27b on Hugging Face under Apache 2.0 — an open-weights decision model fine-tuned from Alibaba's Qwen3.8-27B — and opened a hosted Decisions API to run it. On October 6 it pushed pplx-decider-v1.1-27b, which now sits at #1 on Hugging Face's new Decision Index leaderboard among 111 open-source Jev replicas — ahead of Jev itself. Same day as the v1 launch, Cloudflare shipped Clef and Clef-flash, and AWS's Strands Labs released Strands Decider 2B. Three decider launches in 24 hours.
This is the what, the why, and the how.
A decision model reads text or images the way a multimodal language model does — but instead of writing a reply, it returns typed answers with calibrated probabilities. Perplexity's docs are blunt about the boundary: it does not write replies, generate code, or explain its reasoning; your code does the reasoning with the numbers it returns.
The Decisions API (POST https://api.perplexity.ai/v1/decisions) supports three question types, and they map almost one-to-one onto the primitives Jev introduced in September:
| Type | You ask | You get |
|---|---|---|
noul |
A yes/no question | The probability of yes, 0–1 |
choice |
Pick one of your options (1–255) | A probability for every option, plus the most likely one |
score |
Rate content on an ordered rubric (up to 10 levels) | A probability per level, plus an expected score that can fall between levels |
The details in the docs are telling. One request can carry a shared state (text, JSON, or base64 images — the API never fetches a URL, and an http:// image link simply returns a 400) and up to 128 independent questions against it, each with its own type. Input can run to just under 262,144 tokens. And the answers come back small enough to be funny: the docs' sample request — three questions about a product review — bills 367 input tokens and 3 output tokens.
Here's the shape of a real response from the quickstart: asked whether a review reports a defect, the model returns 0.9424. Asked for sentiment, it returns mixed with a top probability of 0.95 and a separate confidence of 0.93 — confidence is the model's own certainty estimate, and it drops when the runner-up option is close. Asked to grade severity on a three-level rubric, it returns 1.78, a probability-weighted average that lands between "Inconvenient" and "Product unusable." That last one is the quiet highlight: because the score is an expected value, software gets a number that can sit between two levels instead of a forced pick.
Why does this category exist at all? Because the default way engineers have been getting decisions out of large language models is wasteful: you ask a chat model "which team should handle this ticket?", it politely writes you a paragraph of preamble, emits JSON you must parse and validate, and charges you generation tokens for prose nobody reads. For a pipeline that classifies millions of tickets, routes RAG chunks, or gates agent actions, that paragraph is pure tax — latency, cost, and parsing failures all at once.
Jev's founders named the problem "System One vs. System Two": chat models are slow deliberators, but software automation mostly needs fast, calibrated judgments. Perplexity's entry matters for three concrete reasons:
1. It's open weights, Apache 2.0. You can pull the 52.2 GB repository, run it in your own data center, fine-tune it further, and ship it inside a product. Data never leaves your network.
2. It beats the closed original — on the leaderboard that matters. On Hugging Face's Decision Index 0.3, v1.1 scores 62.8, ahead of Fastino GLiDE no-thinking (60.2), Jev itself (60.1), and Torchcast Decision 27B (59.9). The index blends 20% public benchmarks with 50% private same-capability tests and 30% private new-domain tasks — the private portion is never published, so public-set overfitting alone can't win it.
3. The price collapsed. The Decisions API now bills $0.02 per million input tokens with output free — half of what v1 cost at launch ($0.04) and one-fifth of OpenAI's competing Decisions API ($0.10 per million input, no output fee, model gpt-6-luna, public beta ahead of GA "in weeks").
Perplexity's own 11-benchmark panel (7,210 samples, vendor-measured) puts pplx-decider-v1 at 85.71% overall versus Jev's 84.51%, with the widest gap on RAGTruth — judging whether retrieved passages actually support an answer — at 88.80% versus 77.27%. The base Qwen3.8-27B, for reference, scores 74.76% on the same panel; the fine-tune adds roughly 11 points. Treat all of these numbers as the company's own measurements, not an independent rerun — the docs publish no third-party audit.
The engineering story is where this gets interesting for practitioners, because Perplexity didn't just prompt-tune a Qwen model into a judge — it performed structural surgery:
lm_head is gone. In its place sits a dedicated decision head — readout.safetensors contains a [255, 5120] BF16 matrix, which is why a single question tops out at 255 options. The model also ships a stored calibration temperature that the official DecisionModel.predict applies automatically; if you compute probabilities from raw logits yourself, the docs' guidance is to apply it once and normalize only over the question's valid options.tasksource collection, which the model card thanks by name. Version-over-version, v1.1 lifted the model-card Decision Index score from 56.4 to 61.56, with the biggest category gains in language (63.5 → 69.45), retrieval (54.9 → 61.26), and arts (39.4 → 44.66). Knowledge is the holdout — v1.1 scores 48.18 there, still below Jev's 51.4 — and tools dipped slightly (79.3 → 78.88).There's also a confession hiding in the package name: the inference code lives in a Python package called autojev. The yes/no type is called noul — spelled identically to Jev's binary type. Perplexity didn't just compete with Jev; it built a high-profile member of the open-source replication movement Jev inspired, and won it.
Self-hosting is real but not casual. The requirements: Python 3.12+, a CUDA GPU, and roughly 49 GiB just for the weights plus working memory on top. The practical targets are an 80 GB A100/H100 or a 96 GB RTX PRO 6000 — the Decision Index leaderboard itself was run on a single RTX PRO 6000. BF16 weights will not fit on 24 or 32 GB consumer cards; community quantizations of v1 already exist, and v1.1 quants are presumably coming. The official inference code is CUDA-only, so Mac users are out of luck for now, and v1.1 is gated — you'll need to log in to Hugging Face and request access.
One trap deserves its own paragraph: you can't just drop these weights into vLLM and serve them as a Qwen model. The full-vocabulary lm_head doesn't exist. If your inference stack demands a standard Qwen3_5ForConditionalGeneration, the model card describes an export procedure — mapping each decision-head row back to its vocabulary token row — and stresses you must also preserve the non-causal attention, or the accuracy numbers won't reproduce. Perplexity's own advice is to use the bundled model.py, which it says was copied byte-for-byte from the training and evaluation setup.
The comparison the Chinese tech press has been running all week is against OpenAI's Decisions API, announced at DevDay. Both do typed answers with probabilities over shared input. The differences are structural:
noul on one side and predicate on the other; options live in a criteria dictionary versus a choices array; scoring uses levels.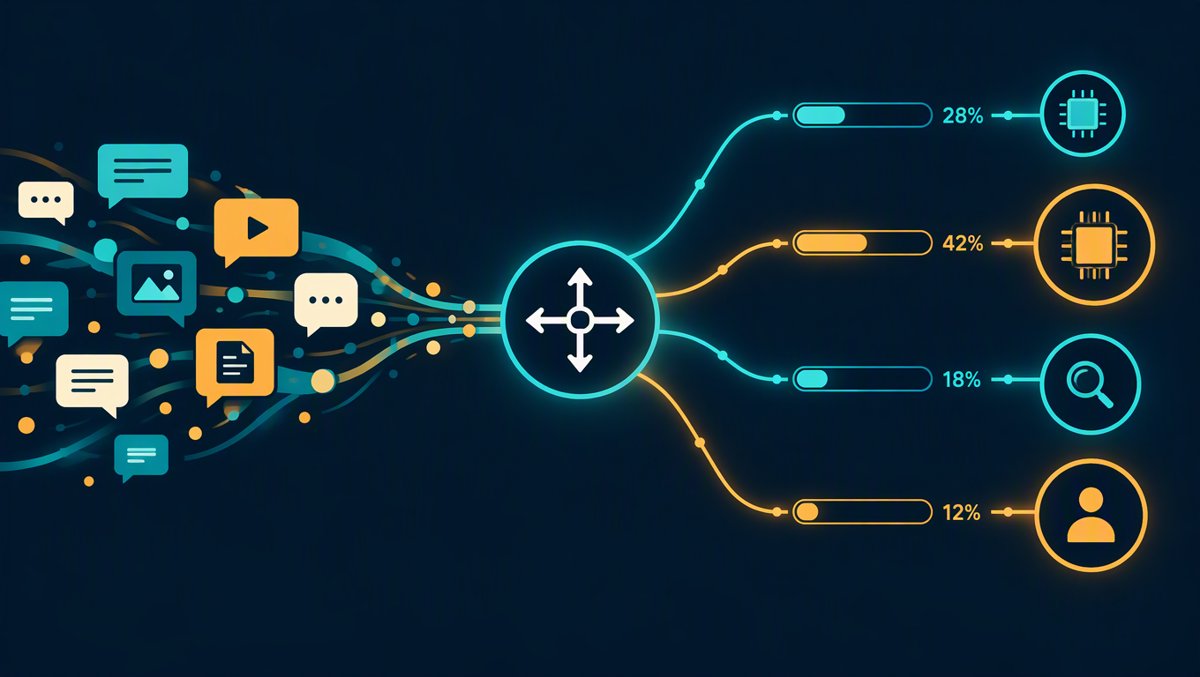
Zoom out from Perplexity and the real headline is the chassis. Qwen3.8-27B — Alibaba's dense, natively multimodal 27-billion-parameter model, released August 14 under Apache 2.0 — has become the default engine of the entire decision-model wave. Perplexity's own model page listed 478 fine-tunes derived from it. Scroll the Decision Index top ten and you find Torchcast Decision 27B, Kev 27B, JEV-27B, Eikos 27B-FP8 (a Qwen3.8-27B LoRA), simple-jev, reflex — a wall of 27B builds, many with the base model's name literally in the title.
The reasons are unglamorous and decisive: the semantic foundation is thick enough that a decision head on top beats a closed frontier model; 27B dense parameters fit the "one big GPU" sweet spot that mid-size companies actually own; and the Apache 2.0 license lets anyone — including a US search company — commercialize the result without sending Alibaba a check. Meanwhile the same base model is simultaneously powering agentic coding fine-tunes, computer-use variants, and local deployments. It is the closest thing open AI currently has to a common platform.
The docs' own framing, plus a week of community experimentation, points to a consistent pattern: decision models go at the front of the agent pipeline, as a triage desk. Incoming request → decider → route to a cheap small model, a frontier model, a search tool, or a human — with thresholds tuned on your own labeled samples, priced by asymmetric error cost (the price of wrongly auto-approving a risky action is not the price of wrongly queueing a normal one).
Beyond routing, the highest-signal fits map directly onto the benchmark panel: RAG relevance gating (where decider's margin over Jev is widest), support-ticket classification and urgency scoring, content-moderation guardrails around agent actions, and vision checks like product-image damage detection. Anywhere you would have prompted a chat model for a label and parsed the reply, there is now a cheaper, faster, calibrated alternative.
Three weeks ago, decision models were a clever idea from a $200 million startup with a closed model and a memorable name. Today the best open one runs on hardware mid-size companies already have, costs a fiftieth of a frontier chat model per judgment, and carries an Apache 2.0 license with a big US company's name on the commit history. The Jev moment has become the Jev category, and the category is being built — loudly — on an Alibaba chassis.
For builders, the move is straightforward: the next time you write a prompt asking a language model to "classify the following and reply in JSON," ask yourself whether a 20-millisecond probability machine should be doing that job instead. The triage desk is now open source. Your routing table will know what to do.
Sources: Hugging Face model cards for pplx-decider-v1-27b and v1.1-27b; Perplexity Decisions API documentation (docs.perplexity.ai); Perplexity community announcement for v1.1; AI Weekly's October 1 launch coverage; OpenRouter listing for pplx-decider-v1-27b; the original Chinese analysis by "Ai学习的老章" (woshipm.com, October 8); Hacker News via Algolia. Context: John's September 23 deep dive on TypeSafe's Jev.